OneOcr (NuGet, GitHub) is a free, open-source (MIT OR Apache-2.0) .NET OCR library from Recursive AI. On .NET 10, read text and boxes from an OcrPage instead of parsing Tesseract output.
OneOcr needs no native dependencies or tessdata folder and is tested on Windows x64, Linux x64 and Arm64, and macOS Arm64.
The bundled model reads Latin, Greek, and Cyrillic, but not CJK, Arabic, or Indic scripts.
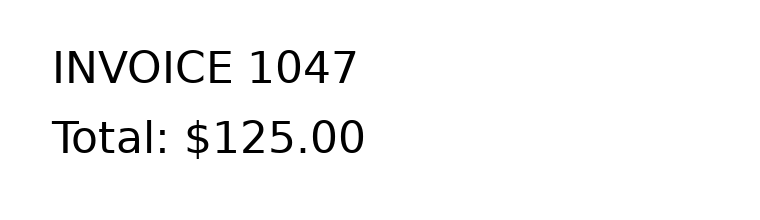
dotnet add package RecursiveAI.OneOcrSave invoice.png in the .NET 10 console project. Replace Program.cs and run dotnet run. OneOcr brings in OneImage for Image.Load.
using System.Globalization;
using OneImage;
using OneOcr;

var engine = OcrEngine.LoadBundled();
var image = Image.Load("invoice.png");
var page = image.Ocr(engine);

Console.WriteLine(page.Text);
var count = page.Words.Count;
Console.WriteLine($"Words: {count}");
var first = page.Words[0];
var x = first.Box.Left;
var y = first.Box.Top;
var score = first.Confidence;
var line = string.Create(
    CultureInfo.InvariantCulture,
    $"{first.Text}: x={x:F0}, " +
    $"y={y:F0}, confidence={score:F2}");
Console.WriteLine(line);
INVOICE 1047
Total: $125.00
Words: 4
INVOICE: x=56, y=50, confidence=0.97
The NuGet package installs the bundled models automatically. Load OcrEngine once at startup and reuse it. The engine is immutable and thread-safe. If you need both text and geometry, read both off the same page rather than calling OCR twice.
Run the Tesseract baseline
This baseline uses the released Ubuntu Tesseract 5.5.0 package and the tesseract-ocr-eng language data. It uses the official CLI, not a .NET wrapper. If your C# app shells out to Tesseract, run these commands in the same directory to check its text and TSV inputs before changing the app.
tesseract invoice.png stdout -l eng
tesseract invoice.png stdout -l eng tsv
INVOICE 1047
Total: $125.00
The TSV output includes layout rows as well as words. Here are the box coordinates, confidence, and text from the first word row (level=5), with spaces for alignment:
left top width height conf      text
56   50  175   33     95.905121 INVOICE
Map settings and results
The Tesseract calls below follow its CLI documentation. The OneOcr fields and limits are from the 1.0.0 migration reference and the page model specification.
| Tesseract 5.5.0 | OneOcr 1.0.0 |
|---|---|
Executable, tessdata and -l eng | Install the NuGet package and call OcrEngine.LoadBundled(). No tessdata directory or language argument. The bundled recognizer reads Latin, Greek, and Cyrillic together; it does not cover CJK, Arabic, or Indic scripts. |
--psm layout hint | No mode-for-mode replacement. Start with image.Ocr(engine); the detector finds lines and the layout code orders them. If you already crop a single line, pass the crop and consider disabling DetectOrientation and Deskew via OcrOptions. |
| Plain text output | image.ToText(engine) for reading-order text only, or page.Text if you already have an OcrPage. The latter puts blank lines between blocks. Compare whitespace and reading order if downstream code splits on newlines. |
| TSV word rows | Read page.Words, or walk page.Blocks → block.Lines → line.Words to keep grouping. There is no drop-in TSV schema: don’t carry over Tesseract’s paragraph and row IDs as OneOcr IDs. |
left, top, width, height | Use word.Box.Left and Top; subtract left from right and top from bottom for width and height. Image coordinates are pixels from the top-left, y down. The same coordinate convention does not guarantee the same boxes. |
TSV word conf (0–100) | word.Confidence is a calibrated 0–1 estimate that the entire word is correct. The scores are not equivalent after rescaling. Retune any review threshold on labeled images from your pipeline. |
| hOCR or searchable PDF output | OneOcr can serialize structured results as oneocr.page JSON, not hOCR. It does not write searchable PDFs in 1.0.0. Keep the existing writer if a consumer requires either format. |
Check what your downstream code depends on
- Text: replay your existing image fixtures. Check punctuation, whitespace, and reading order before changing anything that splits text into records.
- Geometry: check overlays on a rotated scan and a multi-column page. Keep grouping from the page model if you currently use TSV block and line numbers.
- Review rules: verify supported scripts and tune confidence thresholds against known text. The example’s
0.97is a score for one word, not an accuracy figure for the page or a migration target.
For engine setup and other input formats, see OneOcr getting started. The migration reference also covers orientation, DPI, and other CLI settings.