To redact a PDF in C#, find the areas to remove (usually from the word positions that text extraction gives you), pass them to doc.Redact and save. OnePDF rewrites the page content: the glyphs, vector shapes and image pixels inside each area are deleted from the file, and a black box is drawn where they were. Afterwards, text extraction, copy and paste and other PDF readers find nothing of what was removed. If any page can’t be read completely, nothing is changed and you get an exception naming the page. OnePDF is pure C#, licensed MIT OR Apache-2.0. Every sample was compiled and run against OnePDF 1.11.0 on .NET 10 and the results checked with pdftotext.
Why a black box isn’t redaction
The mistake behind most redaction leaks is drawing a black rectangle over the text. The page looks redacted, but the text is still in the file, under the box:
using OnePdf;

// The common mistake: draw a black box over the text and save.
using (PdfDocument doc = PdfDocument.Open("report.pdf", new PdfOpenOptions { AllowEditing = true }))
{
    using (PdfPageContentBuilder b = doc.Pages[0].BeginContent())
    {
        b.SetFillGray(0);
        b.Rectangle(54, 640, 504, 30);                       // covers the "Prepared by ..." line
        b.Fill();
        b.Commit();
    }
    doc.Save("report-boxed.pdf");
}

using PdfDocument boxed = PdfDocument.Open("report-boxed.pdf");
string text = boxed.Pages[0].ExtractText().Text;
Console.WriteLine($"looks redacted, but the text still contains \"4471-2290\": {text.Contains("4471-2290")}");
looks redacted, but the text still contains "4471-2290": TrueSelect-all and copy in a PDF viewer, a search engine’s indexer or pdftotext reads it straight out. Real redaction has to remove the content from the page’s content stream, and then from everywhere else the text might be repeated: metadata, bookmarks, form values, annotations, alternate text.
Before you start
dotnet new console -o PdfRedact
cd PdfRedact
dotnet add package RecursiveAI.OnePdf --version 1.11.0
OnePDF targets .NET 10. The samples redact report.pdf, a six-page report where each page starts “Prepared by Jane Doe, account 4471-2290.”
Find and redact names and numbers
Redaction works on areas of a page. To redact text, find its words with text extraction, which returns every word with its bounding box, and turn the matches into areas. This sample removes every account number, matched with a regular expression, and every “Jane Doe”:
using System.Text.RegularExpressions;
using OnePdf;
using OnePdf.Text;

var accountNumber = new Regex(@"^\d{4}-\d{4}$");
string[] name = ["Jane", "Doe"];

using PdfDocument doc = PdfDocument.Open("report.pdf", new PdfOpenOptions { AllowEditing = true });

// 1. Find what to remove: every account number and every "Jane Doe", as boxes on their pages.
var regions = new List<PdfRedactionRegion>();
for (int p = 0; p < doc.PageCount; p++)
{
    foreach (PdfTextLine line in doc.Pages[p].ExtractText().Blocks.SelectMany(b => b.Lines))
    {
        IReadOnlyList<PdfTextWord> words = line.Words;
        for (int i = 0; i < words.Count; i++)
        {
            if (accountNumber.IsMatch(Clean(words[i].Text)))
                regions.Add(new PdfRedactionRegion(p, words[i].Bounds));

            if (i + name.Length <= words.Count && name.Select((s, k) => Clean(words[i + k].Text) == s).All(m => m))
                regions.Add(new PdfRedactionRegion(p, Union(words.Skip(i).Take(name.Length))));
        }
    }
}

// 2. Remove it, cover each spot with a black box, and clear the name from the metadata too.
PdfRedactionResult result = doc.Redact(regions, new PdfRedactionOptions
{
    Overlay = new PdfRedactionOverlay(),
    MetadataTerms = ["Jane Doe"],
});
doc.Save("report-redacted.pdf");                              // a full save: SaveIncremental is refused after Redact
Console.WriteLine($"{regions.Count} areas, {result.GlyphsRemoved} glyphs removed on {result.PagesProcessed} pages");

// 3. Check: nothing of it is left in the extracted text.
using PdfDocument check = PdfDocument.Open("report-redacted.pdf");
string all = string.Concat(check.ExtractText().Select(page => page.Text));
Console.WriteLine($"\"Jane\" left: {all.Contains("Jane")}, \"4471\" left: {all.Contains("4471")}");

static string Clean(string word) => word.TrimEnd(',', '.', ';', ':');

static PdfRectangle Union(IEnumerable<PdfTextWord> words) => new(
    words.Min(w => w.Bounds.Left), words.Min(w => w.Bounds.Bottom),
    words.Max(w => w.Bounds.Right), words.Max(w => w.Bounds.Top));
12 areas, 114 glyphs removed on 6 pages
"Jane" left: False, "4471" left: False
On each page, black boxes now stand where the name and the account number were, punctuation included, since the word boxes take it in. pdftotext report-redacted.pdf finds no “Jane” and no “4471” anywhere in the file, and the rest of each paragraph extracts intact. The remaining text keeps its exact positions: OnePDF rewrites each text operator so the glyphs after a removed word don’t move.
Matching is yours to decide, which is the point: you know whether you need names from a list, a pattern for account or social security numbers, everything inside a form’s box, or areas a reviewer drew in a UI. Two details matter:
- Areas are in the page’s own coordinates, before its rotation. Word boxes from extraction have the rotation applied. On unrotated pages, as here, use them as they are. On a rotated page, convert them first.
- Matching is by position. Only what your areas cover is removed. A word drawn twice needs two areas, and text that exists only as pixels, such as a scan without a text layer, is removed only by blanking the image under the area.
Redact part of an image
An area over an image blanks the pixels inside it and stores the image again. Other pages that share the image keep the original. Here the left half of a logo is removed, filled with white instead of black:
using OnePdf;

// report-images.pdf has a 36 x 36 pt logo at (522, 726) on page 1. Remove its left half.
using PdfDocument doc = PdfDocument.Open("report-images.pdf", new PdfOpenOptions { AllowEditing = true });

var area = new PdfRedactionRegion(0, new PdfRectangle(522, 726, 540, 762)) { FillColor = [1.0] };   // gray 1: white, not black
PdfRedactionResult result = doc.Redact([area]);
doc.Save("report-images-redacted.pdf");

Console.WriteLine($"images blanked: {result.ImagesBlanked}, images removed whole: {result.ImagesRemoved}");
images blanked: 1, images removed whole: 0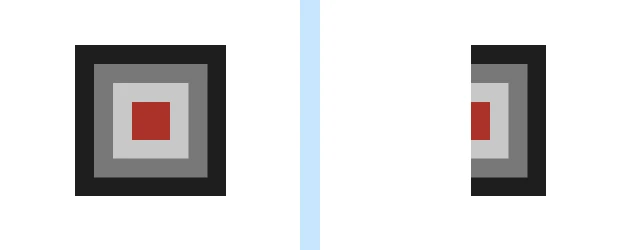
The logo is a PNG, so OnePDF can edit its pixels directly. JPEG, JPEG 2000 and JBIG2 images are blanked when a decoder for that format is registered in PdfRedactionOptions.Decoders. Without one, an image that meets an area is removed whole, so nothing under the area can survive.
What else Redact removes
Inside each area, Redact removes:
- glyphs whose boxes meet the area (or only those wholly inside, with
FullyContainedOnly), - vector paths and shadings that meet it, coordinates included,
- image pixels under it,
- annotations that meet it, with their pop-ups, and the values of form fields whose widgets meet it,
- the
/ActualTextand alternate text of tagged content it removed, so a screen reader can’t read it out either.
Outside the pages, MetadataTerms clears matching entries from the document information, the XMP metadata and bookmark titles. RemoveJavaScript, RemoveEmbeddedFiles and RemoveThumbnails strip those parts, and thumbnails of redacted pages always go. The result object counts everything: glyphs, paths, images blanked and removed, annotations, fields cleared, metadata entries, and whether existing signatures were invalidated.
Files that were marked up for redaction in a PDF editor carry /Redact annotations. doc.ApplyRedactAnnotations() applies them with the same engine and removes the marks.
Rules that keep redaction safe
- Save with
Save, neverSaveIncremental. An incremental save appends changes and keeps the original bytes, text included, in the file’s earlier revision. OnePDF refuses it afterRedact. A full save writes no earlier revisions and no unreferenced objects. - It fails closed. Every page is planned before any is changed. If a page’s content can’t be read completely, because of a damaged stream, a limit, or glyphs that don’t match their string,
RedactthrowsPdfRedactionExceptionnaming the page and the document is left as it was. Anything the rewrite can’t check is not copied through. - Signatures break. A redacted document is a different document.
result.SignaturesInvalidatedsays so. Sign again afterwards if you need to (sign a PDF in C#). - Check the output. Run
pdftotextor OnePDF’s own extraction over the result and search for what you removed, as the sample does. Make that a test in your pipeline.
What stays: the embedded font programs of fonts still used by the remaining text keep all their glyph outlines, including those of removed characters. They hold shapes, not the text, but a font subset made for one page names its glyphs. The full list of what is and isn’t covered is in redaction.
Redaction in other .NET libraries
On page one for this search, most results are commercial products. In iText, redaction is the pdfSweep add-on, described on NuGet as an add-on “that allows you to permanently remove or black out sensitive data from your PDF documents”. Its NuGet listing (5.0.8) links to iText’s legal terms page as its license, where iText Core itself lists the AGPL (iText license). Whichever library you use, verify the output the same way: extract the text of the redacted file and search it.
Where next
- Redact text in a PDF, the short cookbook recipe.
- Get words and their positions, the input to finding what to redact.
- Redaction: exactly what the rewrite does, fails on and doesn’t cover.
- Extract text from a PDF in C#, for reading order, words and lines.