If Arabic in your C# PDF comes out as separate, backwards letters, or Hindi shows a stray virama and vowel signs in the wrong place, the text wasn’t shaped. These scripts need a shaping engine to pick the joined letter forms, the conjuncts and the order of the glyphs. Writing characters one after another with a font isn’t enough. OnePdf.Layout shapes text with the OneFont engine, lays out right-to-left paragraphs and whole right-to-left documents, and falls back from font to font for scripts the main font lacks. It is pure C#, licensed MIT OR Apache-2.0. Every sample was compiled and run against OnePdf.Layout 1.11.0 on .NET 10.
What goes wrong without shaping
The same two strings, “مرحبا بالعالم” (hello world) and “नमस्ते दुनिया”, drawn twice: once with OnePDF’s low-level content builder, which places characters one by one, and once with OnePdf.Layout, which shapes them.
using OnePdf;
using OnePdf.Layout;

const string arabic = "مرحبا بالعالم";
const string hindi = "नमस्ते दुनिया";

// 1. The core content builder: characters placed one after another, no shaping.
using (PdfDocument doc = PdfDocument.CreateEmpty())
{
    PdfCreatedFont arabicFont = doc.AddFont(File.ReadAllBytes("NotoSansArabic-Regular.ttf"));
    PdfCreatedFont hindiFont = doc.AddFont(File.ReadAllBytes("NotoSansDevanagari-Regular.ttf"));
    PdfPage page = doc.InsertBlankPage(0, 300, 120);
    using (PdfPageContentBuilder b = page.BeginContent())
    {
        b.SetFont(arabicFont, 24);
        b.DrawText(arabic, 20, 70);
        b.SetFont(hindiFont, 24);
        b.DrawText(hindi, 20, 25);
        b.Commit();
    }
    doc.Save("unshaped.pdf");
}

// 2. OnePdf.Layout: shaped by OneFont, laid out right to left where the text is.
LayoutDocument.Compose(doc =>
{
    doc.Fonts.Add(File.ReadAllBytes("NotoSansArabic-Regular.ttf"), "Noto Sans Arabic");
    doc.Fonts.Add(File.ReadAllBytes("NotoSansDevanagari-Regular.ttf"), "Noto Sans Devanagari");
    doc.Page(page =>
    {
        page.Size(300, 120).Landscape();
        page.Margin(20);
        page.Content().Column(col =>
        {
            col.Spacing(8);
            col.Item().Text(arabic).FontFamily("Noto Sans Arabic").FontSize(24);
            col.Item().Text(hindi).FontFamily("Noto Sans Devanagari").FontSize(24);
        });
    });
}).Save("shaped.pdf");

Console.WriteLine("wrote unshaped.pdf and shaped.pdf");
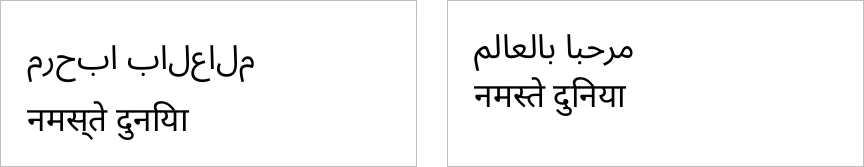
On the left, unshaped.pdf: the Arabic letters are in their isolated forms and run left to right, so the words read backwards, and in “नमस्ते” the स carries a visible virama instead of joining त in a conjunct. On the right, shaped.pdf: the Arabic is joined and runs right to left, and “स्त” is one conjunct. Same fonts, same strings. Only the shaping differs.
Arabic needs each letter in its initial, medial, final or isolated form, plus ligatures such as lam-alef, laid out right to left with numbers and Latin words inside it still left to right. Hindi and the other Indic scripts reorder vowel signs, such as ि, which is typed after its consonant but drawn before it, and merge consonants into conjuncts. Hebrew needs mostly the direction. Thai, Khmer and Myanmar have rules of their own. A PDF library that draws characters straight from the font’s character map gets all of these wrong.
Before you start
dotnet new console -o ArabicPdf
cd ArabicPdf
dotnet add package RecursiveAI.OnePdf.Layout --version 1.11.0
You need fonts that cover the scripts. The samples use Noto Sans Arabic and Noto Sans Devanagari from Google Fonts, both under the SIL Open Font License, which allows embedding. Any TrueType or OpenType font with the script works. The text is embedded as a subset of the glyphs used, so a full font doesn’t bloat the file.
An Arabic document, right to left
doc.RightToLeft() mirrors the whole document: paragraphs start at the right margin, table columns run from right to left, and alignment and list markers follow. Here is a short invoice in Arabic:
using OnePdf;
using OnePdf.Layout;

LayoutDocument.Compose(doc =>
{
    doc.Title("فاتورة INV-2026-0142").Language("ar");
    doc.RightToLeft();                                               // mirror the whole document
    doc.Fonts.Add(File.ReadAllBytes("NotoSansArabic-Regular.ttf"), "Noto Sans Arabic");
    doc.Fonts.FallbackFamilies.Add("Noto Sans Arabic");
    doc.Page(page =>
    {
        page.Size(PageSize.A4);
        page.Margin(54);
        page.Content().Column(col =>
        {
            col.Spacing(10);
            col.Item().Heading(1).Text("فاتورة").FontSize(24).Bold();
            col.Item().Text("رقم الفاتورة: INV-2026-0142");
            col.Item().Table(table =>
            {
                table.Columns(c => { c.Relative(); c.Constant(70); c.Constant(90); });
                table.CellPadding(5);
                table.CellBorder(0.5, Colors.Grey);
                table.HeaderRow(r => { r.Cell().Text("الصنف").Bold(); r.Cell().Text("الكمية").Bold(); r.Cell().Text("المبلغ").Bold(); });
                table.Row(r => { r.Cell().Text("مسح الرصيف"); r.Cell().Text("1"); r.Cell().Text("1,200.00"); });
                table.Row(r => { r.Cell().Text("فحص المرسى"); r.Cell().Text("2"); r.Cell().Text("450.00"); });
                table.FooterRow(r => { r.Cell().Text("الإجمالي").Bold(); r.Cell(); r.Cell().Text("1,650.00").Bold(); });
            });
        });
    });
}).Save("invoice-ar.pdf");

using PdfDocument pdf = PdfDocument.Open("invoice-ar.pdf");
Console.WriteLine(pdf.Pages[0].ExtractText().Text);
فاتورة

رقم الفاتورة: INV-2026-0142

الصنف

الكمية

المبلغ

مسح الرصيف

1

1,200.00

فحص المرسى

2

450.00

الإجمالي

1,650.00
On the page, the heading and text sit at the right margin, the item column is the rightmost one, and the amounts, digits being left to right, read normally. The invoice number “INV-2026-0142” stays in one left-to-right run inside the Arabic line. No item names a font family, so text starts in the default Liberation Sans, which has no Arabic: every Arabic cluster comes from the fallback family, while the Latin letters and digits stay in Liberation Sans. pdffonts lists Noto Sans Arabic and two Liberation Sans faces, all embedded subsets.
Text extraction gives back each line as it was written (above), not in display order, because every run of glyphs is stored with the text it stands for. That makes the PDF searchable and its text copyable in Arabic.
One bidirectional rule catches people out. After Arabic letters, digits count as Arabic numbers, and a hyphen doesn’t join two of them, so “2026-0142” following Arabic text is displayed as “0142-2026”. Browsers do the same, because the Unicode bidirectional algorithm says so. Use a Latin prefix as here, a slash (“2026/0142”), or put the number in its own left-to-right item to keep it in one piece.
Mixed languages in one document
Most documents mix scripts: an English report with a Hindi and an Arabic summary, names in several languages, an address block. Register the fonts as fallback families and OnePdf.Layout picks a font per grapheme cluster, so any line can mix scripts:
using OnePdf;
using OnePdf.Layout;

LayoutDocument report = LayoutDocument.Compose(doc =>
{
    doc.Title("Harbor trial report").Language("en-US");
    doc.Fonts.Add(File.ReadAllBytes("NotoSansArabic-Regular.ttf"), "Noto Sans Arabic");
    doc.Fonts.Add(File.ReadAllBytes("NotoSansDevanagari-Regular.ttf"), "Noto Sans Devanagari");
    doc.Fonts.FallbackFamilies.Add("Noto Sans Arabic");             // tried, cluster by cluster, for characters
    doc.Fonts.FallbackFamilies.Add("Noto Sans Devanagari");         // the main font (Liberation Sans) lacks
    doc.Page(page =>
    {
        page.Margin(54);
        page.Content().Column(col =>
        {
            col.Spacing(10);
            col.Item().Heading(1).Text("Harbor trial report").FontSize(20).Bold();
            col.Item().Text("Summary in Hindi:");
            col.Item().Language("hi").Text("छह दल छह सप्ताह तक बंदरगाह में मछली पकड़ते रहे।");
            col.Item().Text("Summary in Arabic:");
            col.Item().Language("ar").RightToLeft().Text("صادت ستة أطقم في الميناء لمدة ستة أسابيع، وبلغ الصيد 2,220 كغ.");
        });
    });
});

using (FileStream file = File.Create("report-multilingual.pdf"))
    report.Save(file, new PdfSaveOptions { PdfUA = new PdfUAOptions() });   // tagged, with the language of each part

using PdfDocument pdf = PdfDocument.Open("report-multilingual.pdf");
Console.WriteLine(pdf.Pages[0].ExtractText().Text);
Harbor trial report

Summary in Hindi:

छह दल छह सप्ताह तक बंदरगाह में मछली पकड़ते रहे।

Summary in Arabic:

صادت ستة أطقم في الميناء لمدة ستة أسابيع، وبلغ الصيد 2,220 كغ.
- Fallback. The default font, Liberation Sans, has neither Devanagari nor Arabic, so those clusters come from the fallback families, tried in order.
- Direction per item.
RightToLeft()on one item sets its base direction without mirroring the page. The number inside the Arabic sentence stays in left-to-right order. - Language.
Language("hi")andLanguage("ar")mark the language in the tagged structure, so a screen reader switches voice. This file is saved as PDF/UA-1, which the language marks help with (PDF/UA in C#). - Missing glyphs. A character that no registered font has is drawn as the font’s missing-glyph box and reported in the layout’s warnings, instead of silently disappearing.
Arabic, Hindi and other scripts in iText, PDFsharp and QuestPDF
- iText: complex-script shaping is the pdfCalligraph add-on, “for advanced typography features and non-Latin writing systems”, per its NuGet listing (5.1.1), which links to iText’s legal terms page as its license rather than the AGPL of iText Core. See iText license.
- PDFsharp and MigraDoc: OnePDF’s published layout benchmark notes that MigraDoc 6.2.4 “draws Arabic and Devanagari characters unshaped” in its mixed-scripts test (OnePDF README).
- QuestPDF documents a right-to-left content direction,
ContentFromRightToLeft(QuestPDF docs).
Whatever you use, test with your real text: render a page and look at it, and extract the text and compare it with what you wrote.
What doesn’t shape
OnePDF’s core page builder (DrawText, DrawTextBox), which you use to add text to an existing PDF, places characters without shaping, as the first sample shows. It is right for Latin, Greek and Cyrillic. For other scripts, lay the text out with OnePdf.Layout. Hyphenation (RecursiveAI.OnePdf.Hyphenation) covers 26 language variants, none of them Arabic or Hindi.
Where next
- Arabic and Hindi text in a PDF, the short cookbook recipe.
- Layout text: fonts, fallback, bidirectional text and shaping in detail.
- Create a PDF in C# for tables across pages, headers and page numbers.
- OneFont, the shaping engine underneath, on its own.